From paper sources to researchable data
Humanitext OCR
Turn images and PDFs into usable text with AI that takes the document’s context into account. Process many PDFs at once, proofread line by line, and produce searchable PDFs in one continuous workflow.
The app opens in a new tab
What you can do
- Transcribe vertical text, historical orthography, multiple languages, and complex layouts
- Submit up to 50 PDFs at once and let processing continue after you close the browser
- Proofread line by line with the recognised region highlighted in the source image
- Export a searchable, copyable PDF that preserves the appearance of the original
How it works—and how to use it well
Move beyond transcription as a preliminary chore
Humanitext OCR turns images and PDFs into material you can search, correct, and reuse. It is designed for documents that ordinary OCR often distorts: vertical writing, historical forms, handwriting, multilingual pages, and scholarly books with columns, notes, or other complex layouts.
Recognition accuracy is only part of the work. Humanitext OCR brings large-scale processing, verification against the source image, and export to combined text or searchable PDF into a single environment.
Start with one representative page
- Sign in with Google and add an image or PDF.
- Choose how the document should be read. If needed, add an instruction such as “ignore running headers and transcribe only the main text” or “return the table as JSON.”
- Check a test page before starting the full job.
- Download page-level text, combined text, JSON, a searchable PDF, or the other outputs you need.
A free monthly allowance is available, so there is no need to begin with a large collection. Test a page that represents the difficult parts of the document and adjust the instruction before committing the rest. The app displays the current allowance and pricing.
Process many PDFs without keeping a tab open
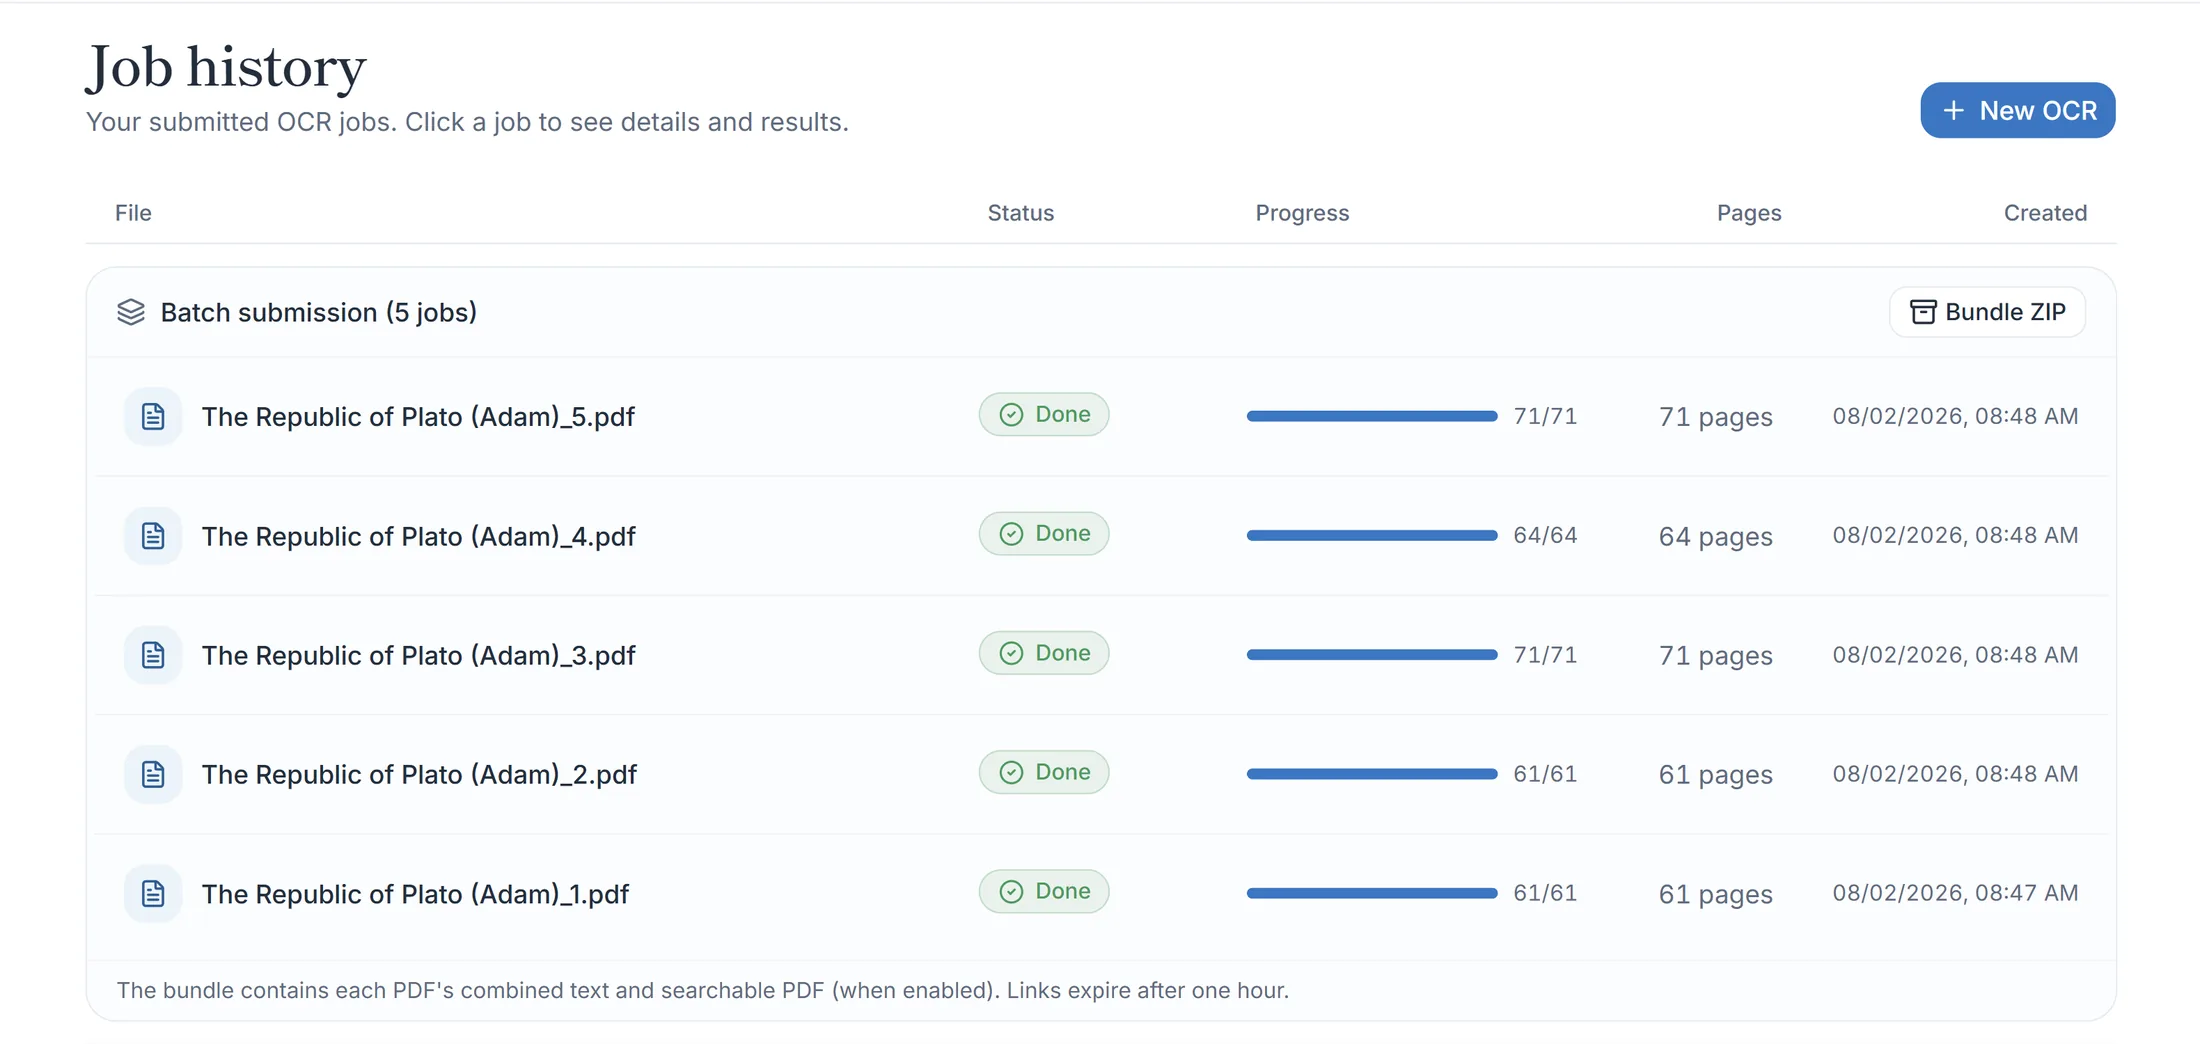
Submit up to 50 PDFs in one batch. Each runs as a cloud job, so processing continues if you close the tab or browser. The job history shows progress and results, and completed files can be downloaded together as a ZIP archive. A batch setting reduces credit use for large collections.
Proofread against the page, one line at a time
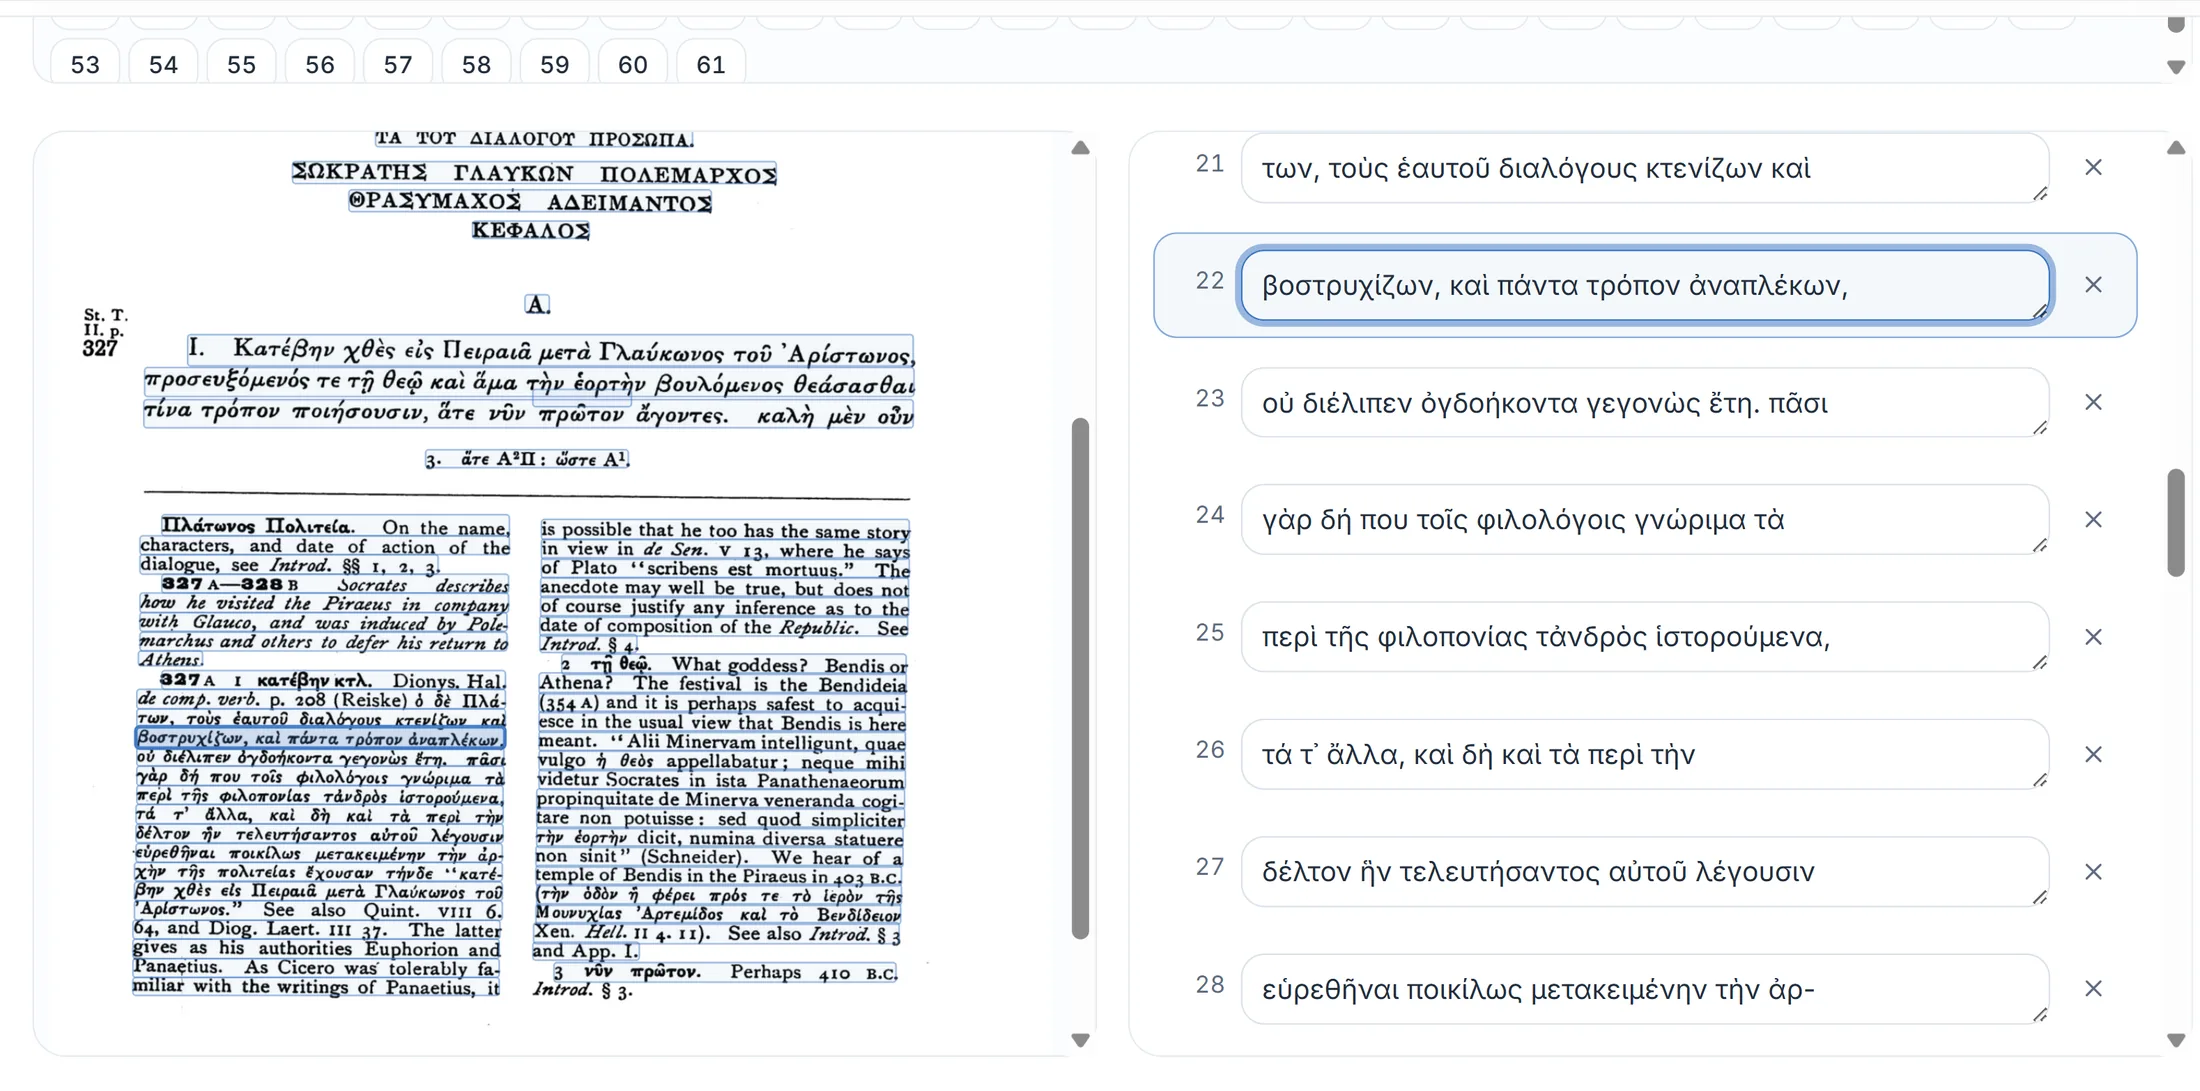
The proofreading view places the source image beside the transcript. Select a line of text and its position is highlighted on the image, making it easier to catch a variant character or a shifted line. Corrections flow through to the combined text and searchable PDF.
Turn a readable PDF into a searchable one
A searchable PDF preserves the page image and its resolution while adding a transparent text layer. Humanitext OCR detects vertical and horizontal lines automatically, allowing text to be searched and copied without replacing the appearance of the source. This is useful when a facsimile must remain visually intact but needs to support discovery and quotation.
AI OCR still makes mistakes. Check names, numbers, and difficult readings against the page before publishing or citing the result. Humanitext OCR does not make editorial judgements for you; it takes on the preparatory work so that you can spend more time making those judgements well.
Take the first step in the app.
Begin small: one question, one work, or one page from a document.